In June Intel OpenVINO team published performance figures for Qwen3.6–35B-A3B on an AI PC. The article inspired me to see I could get it working on a Ultra 7 258V with Arc 140V integrated graphics and serve it as an API over HTTP through OpenVINO Model Server.
Qwen3.6–35B-A3B is a 35 billion parameter Mixture-of-Experts model. In their article, the OpenVINO team used the INT4 compressed model and got it running at 42 to 43 tokens per second on a Core Ultra 7 368H. I have a Core Ultra 7 258V with 32GB of RAM and Arc 140V integrated graphics with no discrete GPU, and I wanted to see how it faired against Intel's results.
It worked. I got the model running around 20 tokens per second, and 90% on a structured extraction benchmark I wrote.
Why a 35B model fits on integrated graphics at all
The maths looks wrong at first. 35 billion parameters at 4 bits is roughly 18GB, and integrated graphics share system memory with everything else running on the machine. Mixture-of-Experts was the feature that made it work.
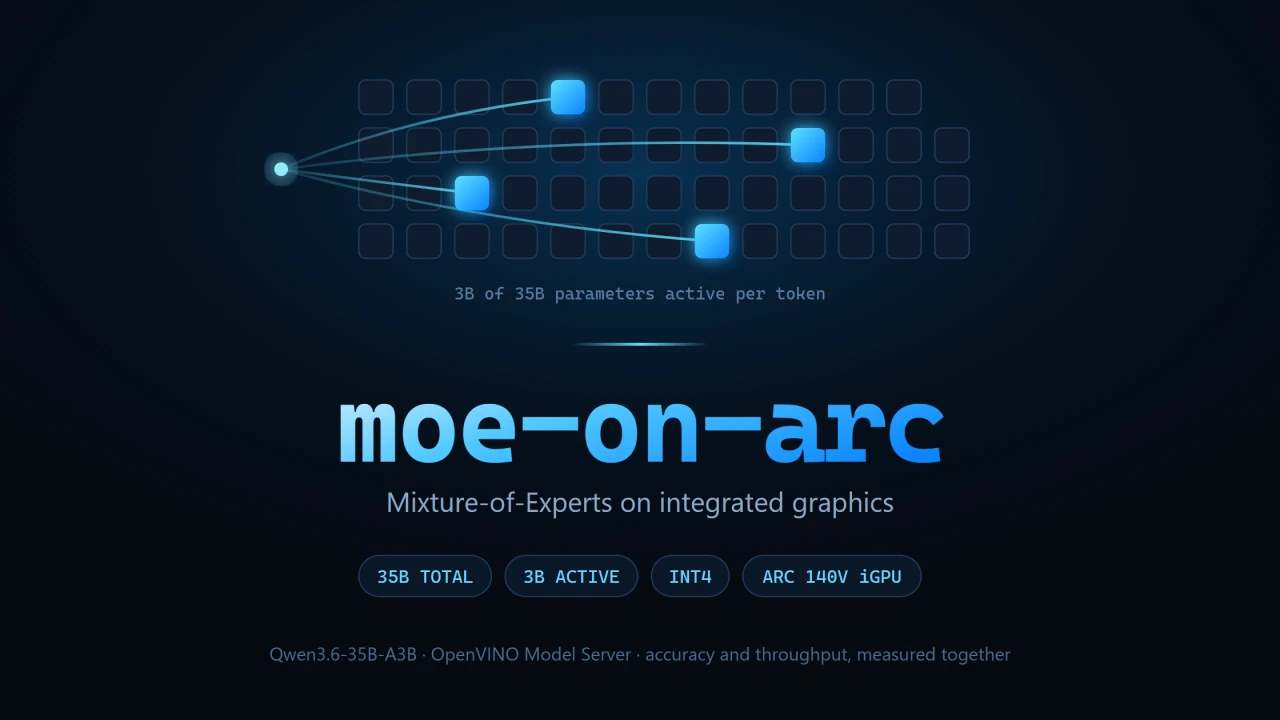
The model has 35B total parameters but activates only about 3B per token. All 35B must sit in memory, but each token only does about 3B worth of work, so it runs at small-model speed while performing well above a 3B model
Sparsity cuts the work per token, but it doesn’t shrink the model. All 35B parameters still have to be stored somewhere. That’s where INT4 quantization comes in. At 4 bits per weight, the model takes up roughly 18 to 20 GB, which fits comfortably in the shared memory of a laptop or a Mac.
Together they make a 35B class model a realistic laptop workload. The theory is sound. Getting there took longer than I expected, and none of the difficulty was the model.
Finding the memory ceiling
My first real attempt failed with CL_OUT_OF_RESOURCES. I had 24.8GB of system RAM free and 18.3GB of weights, so this made no sense to me.
Windows exposes roughly half of system RAM as the shared graphics budget. On a 32GB machine that is 16GB. My weights were 18.3GB. How much system RAM was free did not matter, because the GPU could not address it.
OpenVINO's FULL_DEVICE_NAME reported Intel(R) Arc(TM) 140V GPU (16GB), and it kept reporting 16GB after I raised the limit. That string is set at enumeration and reflects the default allocation, so the property to query is GPU_DEVICE_TOTAL_MEM_SIZE.
import openvino as ov core = ov.Core()
print(core.get_property("GPU", "GPU_DEVICE_TOTAL_MEM_SIZE") / 2**30, "GB")
The fix is a supported control rather than a registry edit. Intel Graphics Software, Graphics, General, Shared GPU Memory Override. I raised it and the queried property went to 22.1GB. That leaves 3.8GB above the weights for the KV cache and activations.
Credit where it is due, the error message itself points at that control. I had spent twenty minutes theorising about registry keys before I read it properly.
It needs the vision pipeline
Qwen3.6–35B-A3B is multimodal. The exported OpenVINO IR is an image-text-to-text graph. LLMPipeline, which is the obvious entry point for text, will not load it. You need VLMPipeline even if you never send an image.
The same applies if you convert the model yourself, where the export needs --task image-text-to-text to produce the full vision-language pipeline. Though I would not bother. The pre-converted OpenVINO/Qwen3.6-35B-A3B-int4-ov artifact is on Hugging Face, and converting a 35B MoE locally costs a lot of RAM and time. I know this because I ran the conversion by mistake while testing, and it exhausted 32GB of RAM trying to upcast the weights to float32.
Check the attention backend
OpenVINO GenAI supports more than one attention implementation. Older releases used Scaled Dot-Product Attention with a single incremental KV cache per sequence. From 2026.2 there is Paged Attention, which stores the cache in fixed size blocks instead of one growing contiguous allocation.
At this scale that is not a detail. Intel’s guidance is direct about it: if you are benchmarking this model and seeing numbers well below the published figures, the attention backend is the first thing to check.
pipe = ov_genai.VLMPipeline(model_path, "GPU", ATTENTION_BACKEND="PA")The payoff in their measurements is latency stability. 23.22ms per token on a short prompt against 23.74ms at 1024 tokens. For a model this size, per-token latency that barely moves as context grows is worth more than the headline throughput number.
The model thinks itself to death
I had the model serving correctly through OVMS. I had tested the endpoint by hand and it returned correct answers. I pointed my benchmark at it and got zero percent. Every field of every case came back empty.
OVMS auto-detects a reasoning parser for Qwen3.6. With that active the model emits its chain of thought into a separate reasoning_content field and leaves content empty until reasoning finishes. Under a modest token cap, it never finishes.
Here is the probe that made it obvious:
{ "finish_reason": "length", "message": { "content": "", "reasoning_content": "Here's a thinking process:\n\n1. **Analyze User Input:**\n - Input: \"Extract vendor from: ACME Ltd, invoice 5\"\n..." }, "usage": { "completion_tokens": 128 } }128 tokens, all of them spent narrating an approach to a one line extraction, and content empty. The model had correctly identified the vendor within its first two sentences of reasoning and then spent 120 more tokens explaining itself.
One request parameter fixes it:
"chat_template_kwargs": { "enable_thinking": false }Accuracy went from 0% to 90%.
For extraction, thinking buys very little. The answer is already in the input and the model is not deducing anything, just locating and reformatting. For genuinely multi-step work the calculation is different. But the default is on, so it is worth checking before you draw conclusions from a low score.
The numbers
Ten invoice extraction cases, six fields each, three repeats. I built the cases to break things rather than to be extracted cleanly: a credit note with a negative total, a PO number sitting next to the invoice number, subtotals directly above grand totals, and dates in ISO, DD/MM/YYYY, Norwegian dotted and “31st January” formats. All synthetic.
| Non-streamed | Streamed | |
| Field accuracy | 90.0% | 90.0% |
| Exact case | 90.0% | 90.0% |
| Decode | n/a | 20.5 tok/s |
| Prefill | n/a | 62 tok/s |
| TTFT (median) | n/a | 2.89 s |
Nine of ten cases came back with all six fields correct. The tenth was a serving bug rather than a wrong answer, which I come to below.
These numbers can’t be compared directly with Intel’s 42 to 43 tok/s. The hardware is different, the serving setup is different, and so is the runtime version. Intel’s own post makes the same point: a benchmark result depends on the runtime version, the model file, the device, the shape of the prompt and the attention path. Decode speed is mostly limited by memory bandwidth, and Lunar Lake’s on-package LPDDR5X gives about 136 GB/s, which would explain part of the gap.
Prefill, which is processing your prompt, is compute bound. Decode, which is generating the response, is memory bandwidth bound. Integrated graphics have far less raw compute than a discrete GPU but a smaller relative bandwidth deficit, so they should be weaker at prefill than at decode.
My prefill figure is prompt tokens divided by time to first token, at prompts of roughly 190 tokens. That includes queueing, tokenisation and the first decode step, so it is a lower bound rather than an isolated measurement. Measuring properly means sweeping across prompt lengths and reading the slope, which I have not done yet.
Directionally it still matters for how you use the machine. Long inputs are likely to cost more than long outputs, so feeding this large documents is where it will suffer. That is not something a single blended tokens per second number would tell you, which is why the harness reports the two separately.
The tenth case
The one case that failed came back cut off mid-value:
"{\n \"vendor\": \"Bondi Surf Supplies Pty Ltd\",\n \"invoice_number\": \"#"I assumed a token cap and doubled it. Identical failure at the identical character position. A token cap that does not move when you raise the cap is not a token cap.
Five theories went in the bin: streaming, temperature, prefix caching, request sequence position, and the compiled graph cache. Each was eliminated by removing it and watching the failure persist.
What was left was the input, so I cut it down to a one field schema and a four character value. With a JSON schema active, generation stops when the model tries to emit a # inside a string. Five out of five, and it never once produced the character. Controls with %, @ and & pass twenty out of twenty. The same input with no schema emits # happily and keeps going.
So it is the constrained-decoding path, not the model. I have reported it upstream with a standalone reproduction script.
It returns finish_reason: "stop" and something that resembles valid JSON. Nothing in the response says anything went wrong. I only caught it because the benchmark compares answers against known values.
What I took from this
Getting from "the model fits" to "the model works" took several hours, and none of it was model quality. Most of the time went on configuration: memory limits, pipeline selection, an attention backend, and a reasoning mode I had left on. The model was competent from the first correct response it gave me.
The hardware is capable and the models are capable. What takes the time is finding the right settings, and several of them fail quietly enough that the model looks like the problem.
The Repo

The harness and the full working configuration are on GitHub as moe-on-arc, Apache 2.0. The README documents each setting with the fix.

Also included is a local UI for running the benchmarks and chatting with the model.
Takeaway
Check how much memory the GPU can use. Windows gives integrated graphics about half of system RAM by default, and the device name keeps showing that default after you change it. Query GPU_DEVICE_TOTAL_MEM_SIZE for the actual limit and raise it with Shared GPU Memory Override in Intel Graphics Software.
Turn thinking off for extraction. The model spent its whole token budget narrating its approach and returned blank answers. Setting enable_thinking: false took my benchmark from 0% to 90%. If every field comes back empty with finish_reason: "length", start there.
Set the attention backend before comparing your numbers with anyone else’s. Paged Attention (ATTENTION_BACKEND="PA") keeps per-token latency flat as the context grows.
Use VLMPipeline even if you only send text. The model is multimodal and LLMPipeline will not load it. Download the pre-converted INT4 artifact.
Test against known answers. The # bug cut a value off mid-string and still returned finish_reason: "stop" with something that looked like valid JSON.
Report prefill and decode separately. Integrated graphics are weaker at reading prompts than at generating replies, so large documents are where this setup will struggle. A single tokens-per-second figure would hide that.
Tested on Core Ultra 7 258V, 32GB LPDDR5X, Arc 140V iGPU, OpenVINO 2026.3, OVMS 2026.3, Transformers 5.2. Model artifact: OpenVINO/Qwen3.6-35B-A3B-int4-ov.
I am an Intel Software Innovator. This is independent work and is not an Intel product. The results and views here are my own and have not been reviewed or endorsed by Intel Corporation or Alibaba Group.
Comments are provided by Disqus, which sets third-party cookies. Choose Accept all in to view and join the discussion.