Bug Hunt Benchmark
Benchmarking locally hosted language models on real debugging work
Model reviews tend to judge chat responses, which is a weak basis for choosing a model to build into a system. This project runs the same debugging tasks against each locally hosted model and compares verified results before that decision is made.
Bug Hunt Benchmark downloads models from the Hugging Face Hub and serves them with runtimes such as llama.cpp, vLLM, SGLang, Ollama, LM Studio or Strata. Any runtime that exposes an OpenAI compatible chat completions API with tool calling can be added, either launched by the application or connected to while already running.
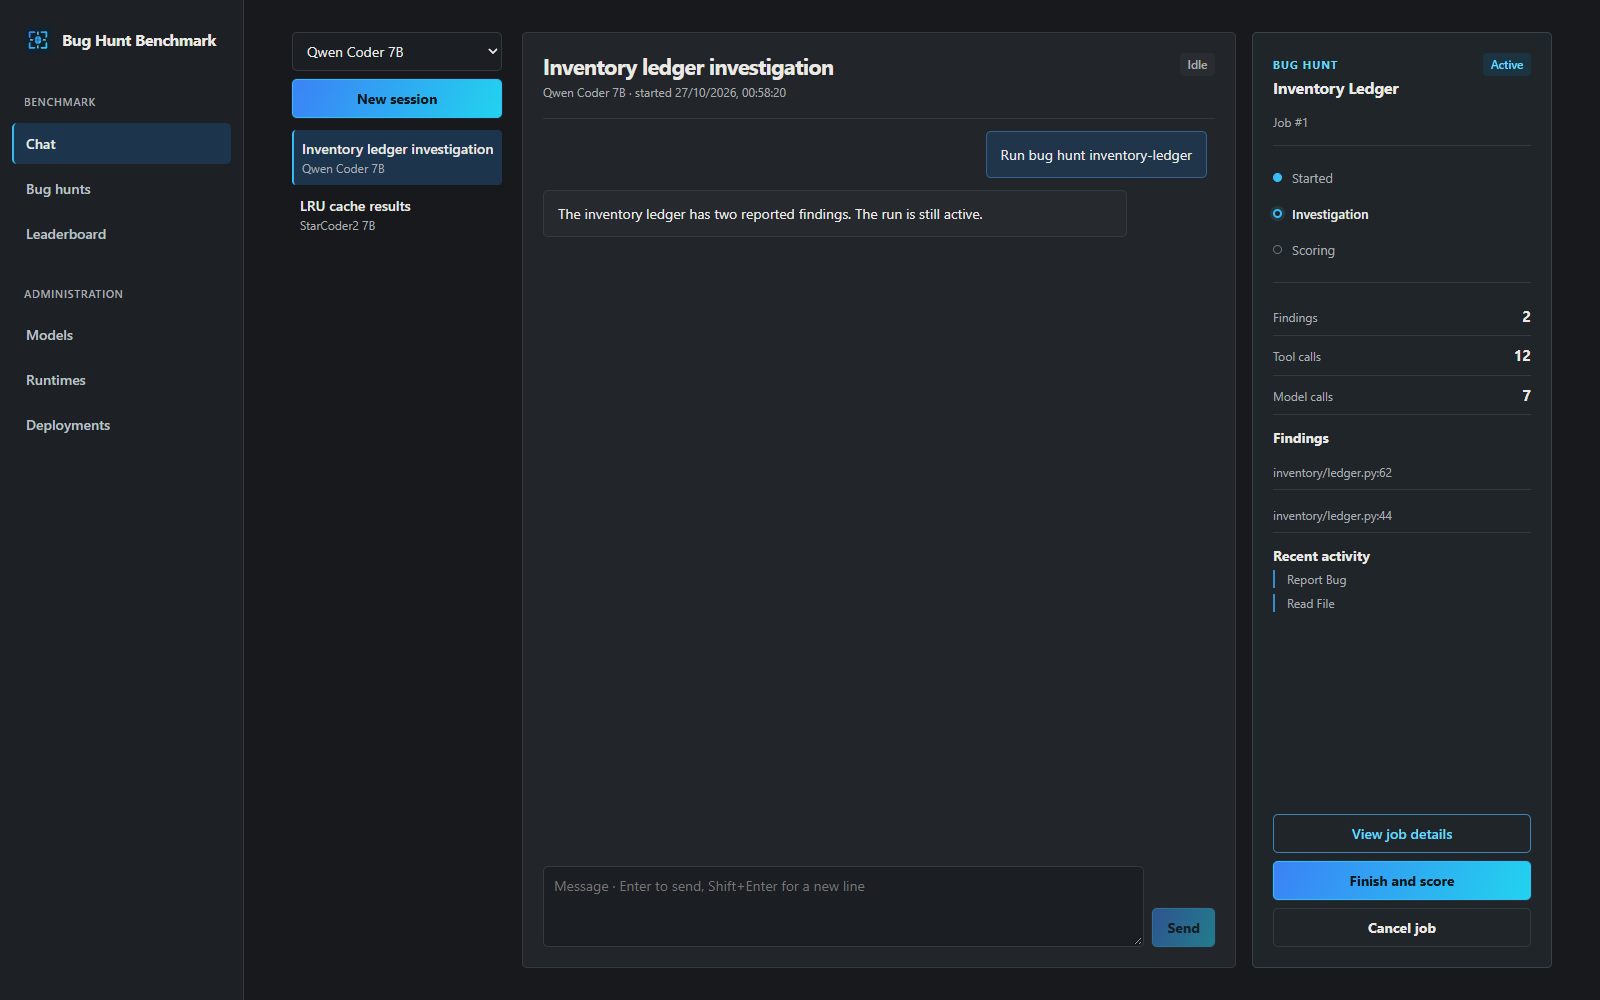
A deployed model is asked in the chat to run a bug hunt. It reads the project through sandboxed tools, reports each defect with a proposed fix and then finishes the hunt. Every proposed fix is applied to a clean copy of the project and checked against a hidden test suite that the model never sees.
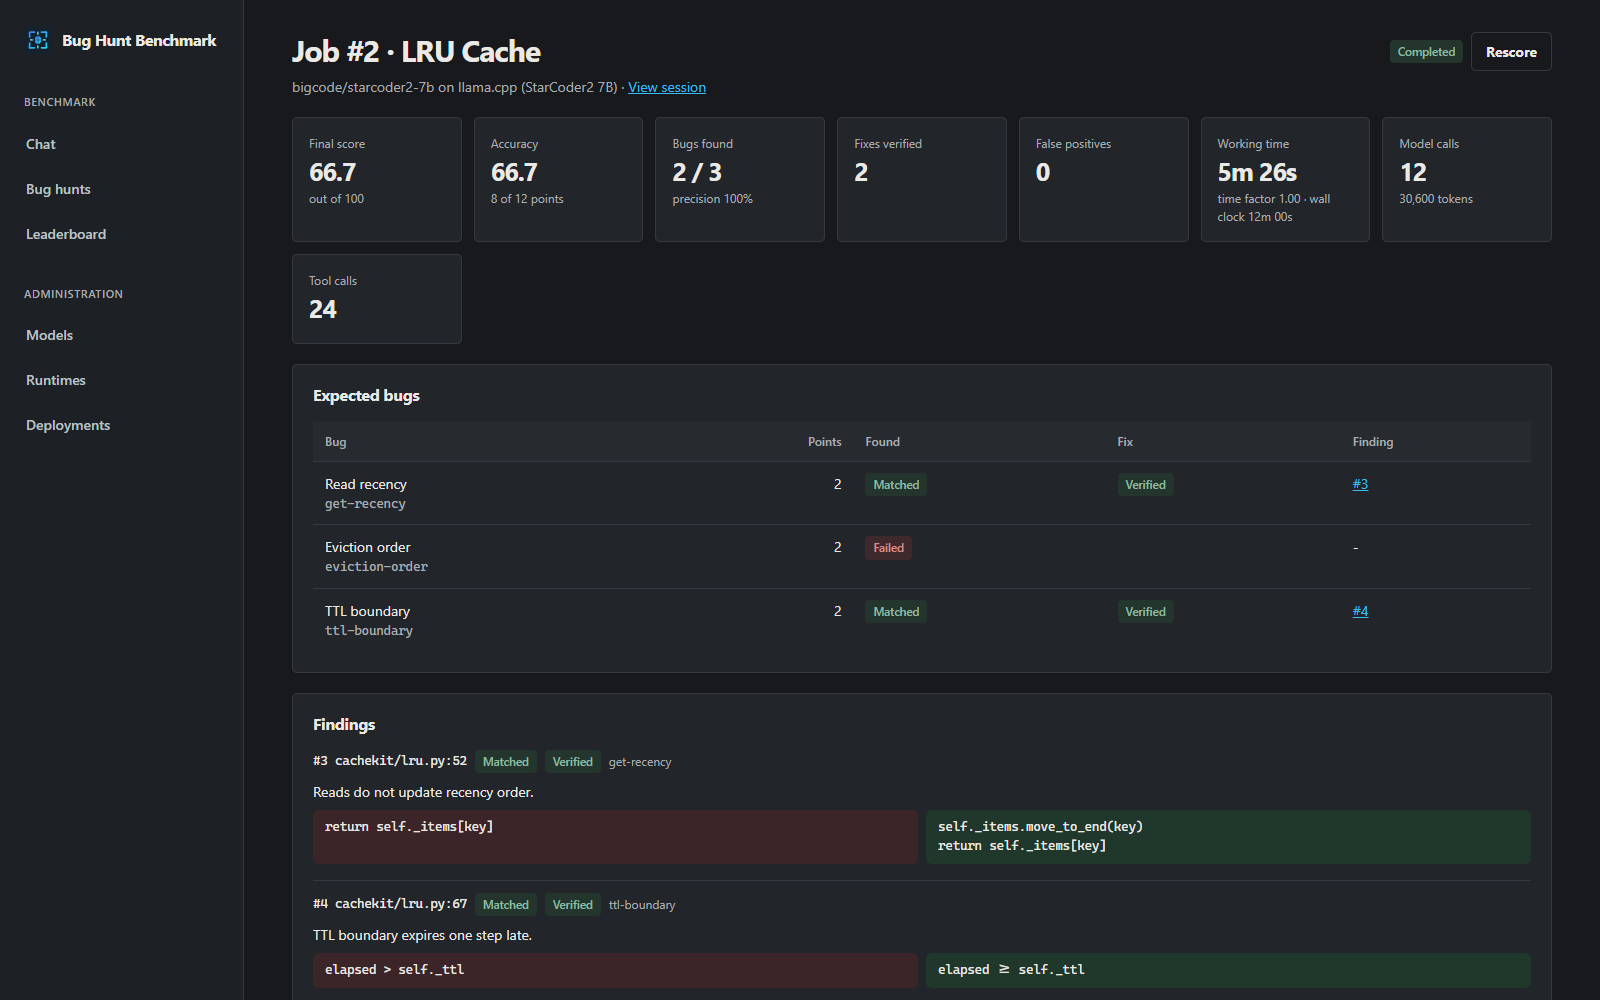
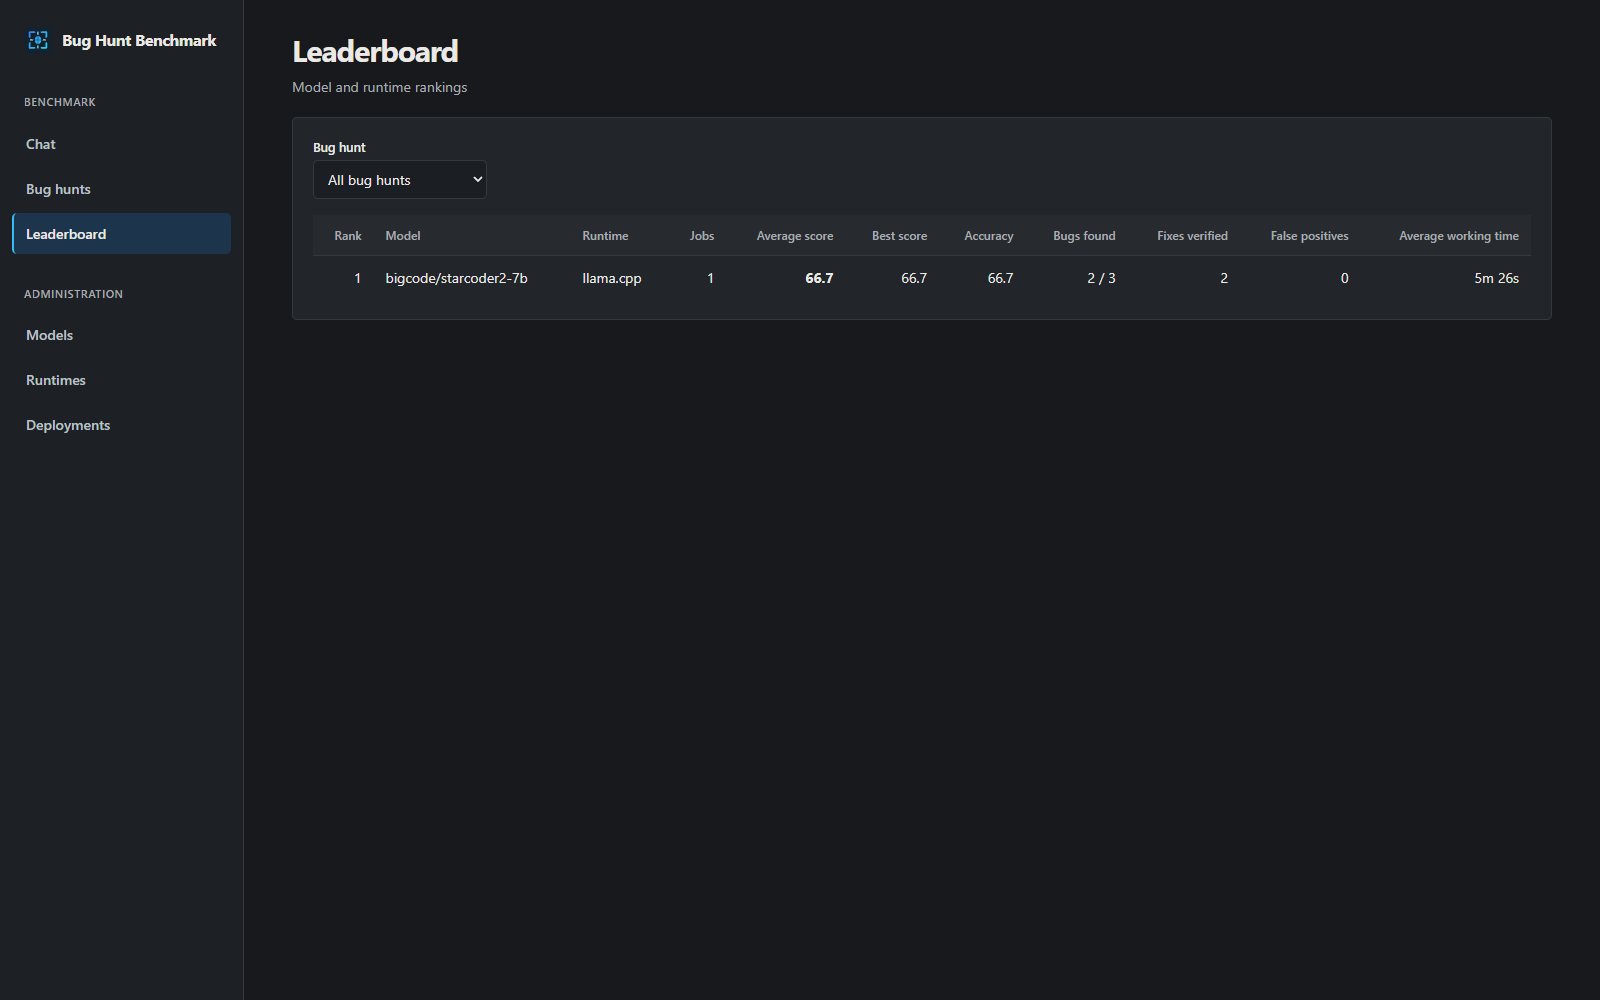
Each bug earns points for detection and again for a verified fix, and false positives deduct points. Accuracy is the share of available points earned, and the final score applies a time factor based on working time against the hunt's time budget. Every conversation, tool call, finding and score is stored, and completed jobs are compared per model and runtime on a leaderboard.
The catalogue ships with six bug hunts from easy to hard, covering stock valuation, text statistics, recurring schedules, cache eviction, decimal money handling and expression parsing. New hunts are added as a directory with source code, hidden tests and a description of each expected bug.
More in Local AI Models.
 Your Voice
A browser application that gives a local language model examples of how you write, a brief for the piece you need, and a workspace where you refine the result together.
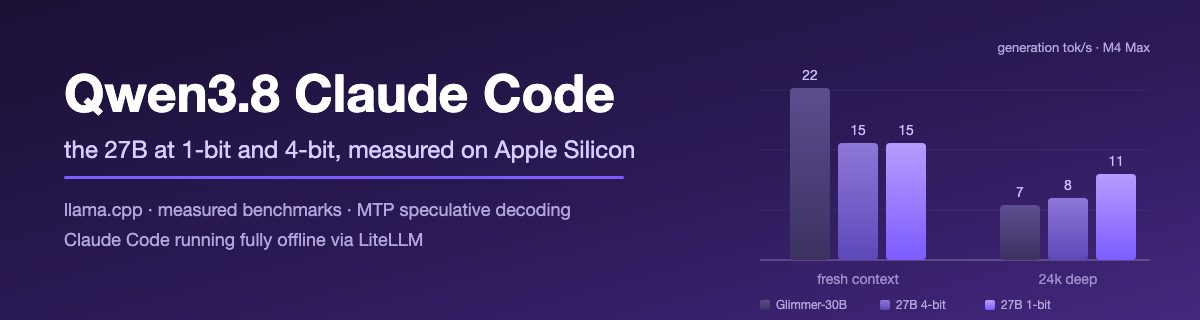 Qwen3.8 Claude Code
Qwen3.8-27B served locally with llama.cpp at 4-bit and 1-bit, benchmarked with and without MTP speculative decoding, and connected to Claude Code through LiteLLM.
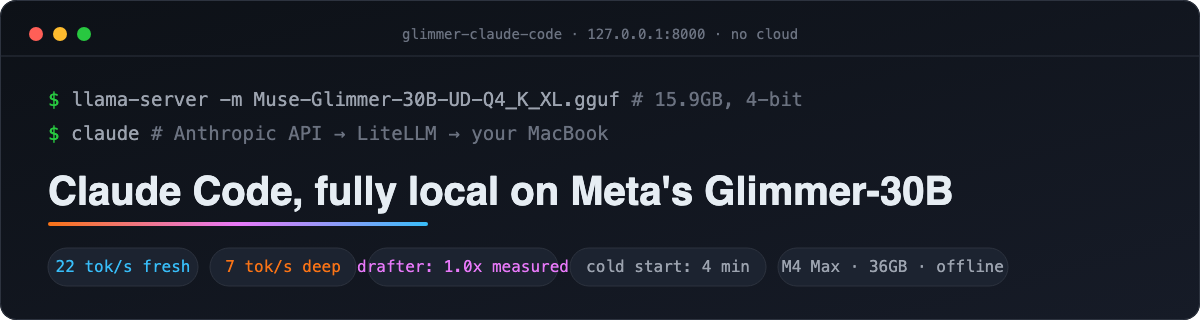 Muse-Glimmer-30B Claude Code
Muse-Glimmer-30B served locally with llama.cpp on an M4 Max, benchmarked with and without dflash speculative decoding, and connected to Claude Code through LiteLLM.
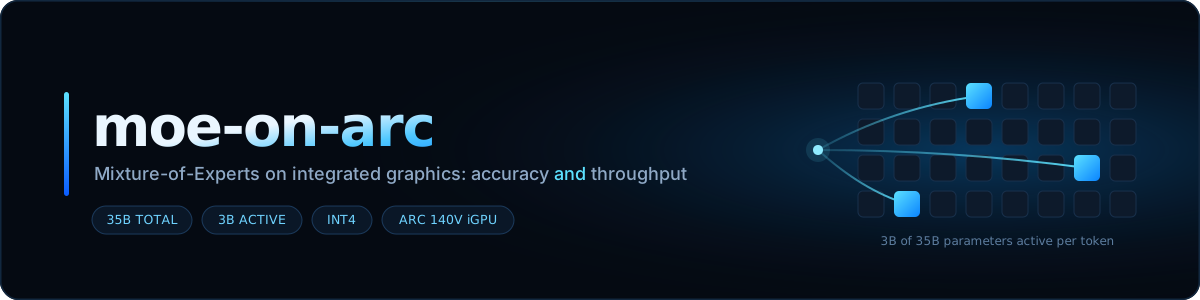 MoE on Arc
A benchmark harness that measures accuracy and throughput together, with a verified configuration for Qwen3.6-35B-A3B on an Intel Arc 140V integrated GPU through OpenVINO Model Server.
Let us build your future
Bring us a plan or just an idea. We will arrange a discovery meeting with you to go through it.