Qwen3.8 Claude Code
Alibaba's Qwen3.8-27B running locally on Apple Silicon with Claude Code
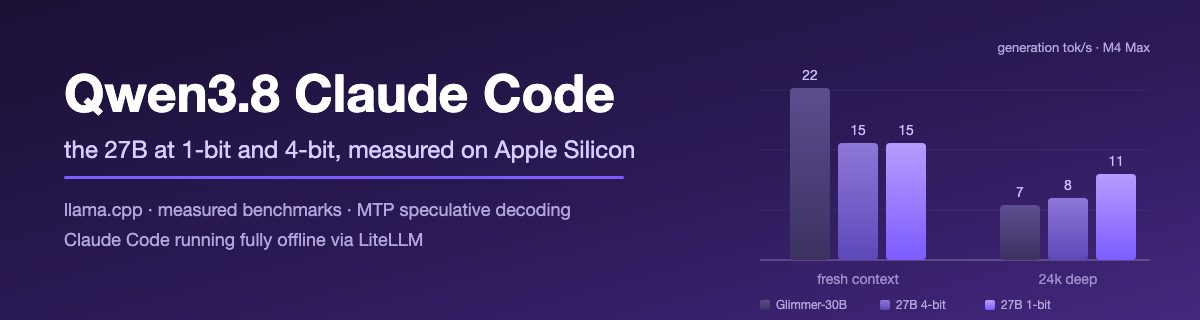
This project runs Qwen3.8-27B on a MacBook Pro with an M4 Max and 36GB of memory, compares the 4-bit and 1-bit quantisations on the same machine, and connects the model to Claude Code so a full coding agent runs with no cloud service.
The project is the follow-up to our Muse-Glimmer-30B work. It downloads the 4-bit quantisation (17.6GB), the 1-bit quantisation (6.2GB) and the model's multi-token prediction (MTP) head, serves the model with llama.cpp, and benchmarks each quantisation with and without MTP speculative decoding.
Both quantisations generate at about 15 tokens per second on a fresh context. The difference is capability: asked to create a deep neural network, the 4-bit model wrote a complete layered implementation, while the 1-bit model did not understand the request. MTP speculation gave a 1.35x speed-up on the 1-bit model and up to 1.56x on long code generation.
The repository includes the benchmark scripts and raw results, a launcher for each serving mode, the LiteLLM configuration for Claude Code, and an HTTP agent harness for using the model from other machines on the network.
Measured results.
- Generation, fresh context
- ~15 tok/s (4-bit and 1-bit)
- Generation, ~24.5k tokens deep
- ~8 tok/s 4-bit, ~11 tok/s 1-bit
- Prompt prefill
- ~137 tok/s 4-bit, ~144 tok/s 1-bit
- MTP speculative decoding
- 1.03x 4-bit, 1.35x 1-bit, up to 1.56x on long code
- Claude Code first response
- 4 min 36 s 4-bit
- Claude Code later turns
- 31 s 4-bit
More in Local AI Models.
 Your Voice
A browser application that gives a local language model examples of how you write, a brief for the piece you need, and a workspace where you refine the result together.
 Bug Hunt Benchmark
A browser application that downloads models from the Hugging Face Hub, serves them with local runtimes, and scores how well each model finds and fixes deliberate defects in small projects.
 Muse-Glimmer-30B Claude Code
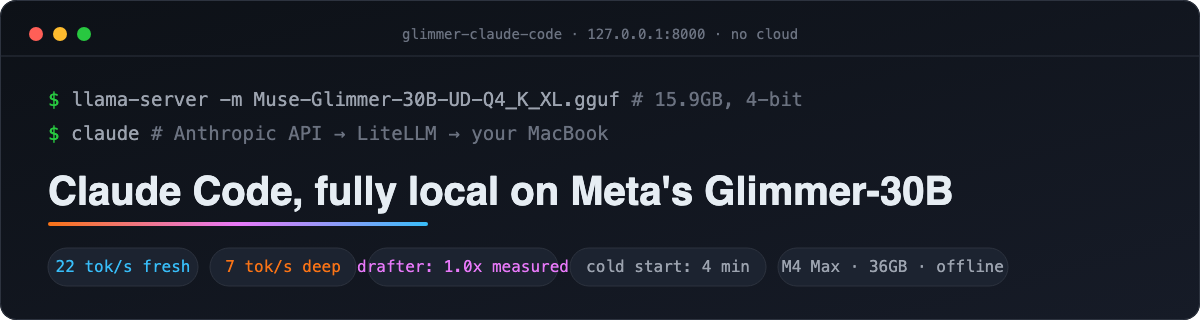
Muse-Glimmer-30B served locally with llama.cpp on an M4 Max, benchmarked with and without dflash speculative decoding, and connected to Claude Code through LiteLLM.
 MoE on Arc
A benchmark harness that measures accuracy and throughput together, with a verified configuration for Qwen3.6-35B-A3B on an Intel Arc 140V integrated GPU through OpenVINO Model Server.
Let us build your future
Bring us a plan or just an idea. We will arrange a discovery meeting with you to go through it.