MoE on Arc
Benchmarking Qwen3.6 MoE on Intel integrated graphics
This project serves the Qwen3.6-35B-A3B mixture-of-experts model, 35 billion parameters with 3 billion active, on the Intel Arc 140V integrated graphics in a Core Ultra 7 258V laptop, and measures the accuracy of its answers alongside its speed.
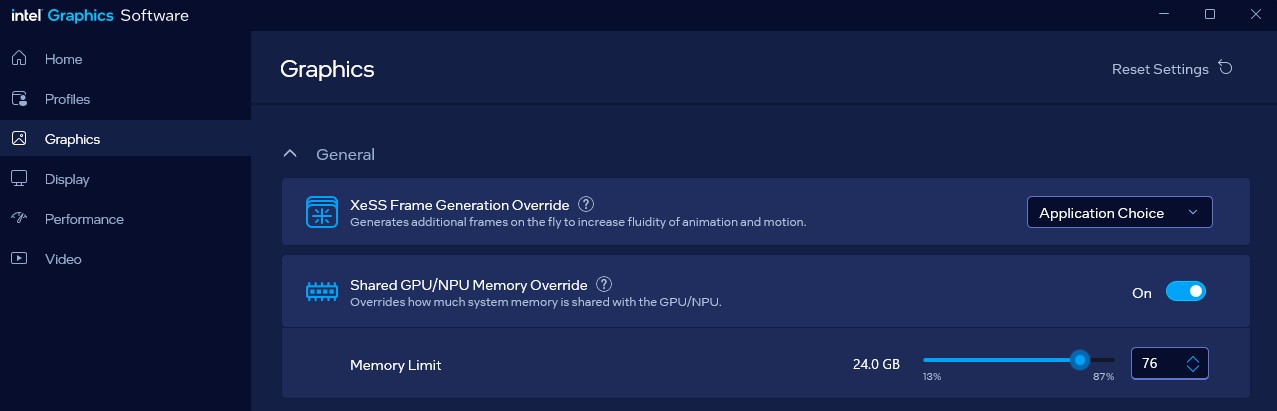
The model is served as an HTTP endpoint through OpenVINO Model Server using the INT4 build published by OpenVINO. The project documents each step, including raising the shared GPU memory limit so the 18.3GB of weights fit, and the server flags needed for tool calling and prefix caching.
The benchmark runs a set of invoice extraction tasks and scores every returned field, so a fast answer that is wrong counts against the model. On the Core Ultra 7 258V it measured 90% field accuracy, 20.5 tokens per second for generation, 62 tokens per second for prefill and a median time to first token of 2.89 seconds.
The harness works with any OpenAI-compatible endpoint, and the repository includes an environment check script, the benchmark tasks and the raw results.
Measured results.
- Field accuracy
- 90.0%
- Exact case, all six fields
- 90.0%
- Decode
- 20.5 tok/s
- Prefill
- 62 tok/s
- Time to first token, median
- 2.89 s
More in Local AI Models.
 Your Voice
A browser application that gives a local language model examples of how you write, a brief for the piece you need, and a workspace where you refine the result together.
 Bug Hunt Benchmark
A browser application that downloads models from the Hugging Face Hub, serves them with local runtimes, and scores how well each model finds and fixes deliberate defects in small projects.
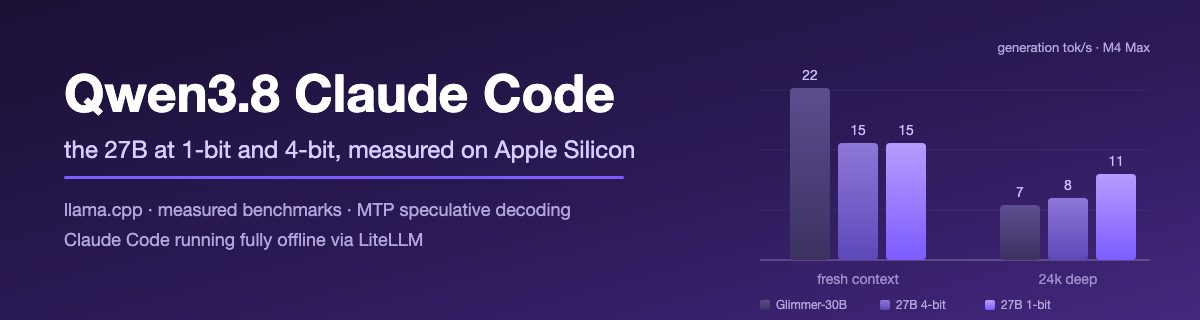 Qwen3.8 Claude Code
Qwen3.8-27B served locally with llama.cpp at 4-bit and 1-bit, benchmarked with and without MTP speculative decoding, and connected to Claude Code through LiteLLM.
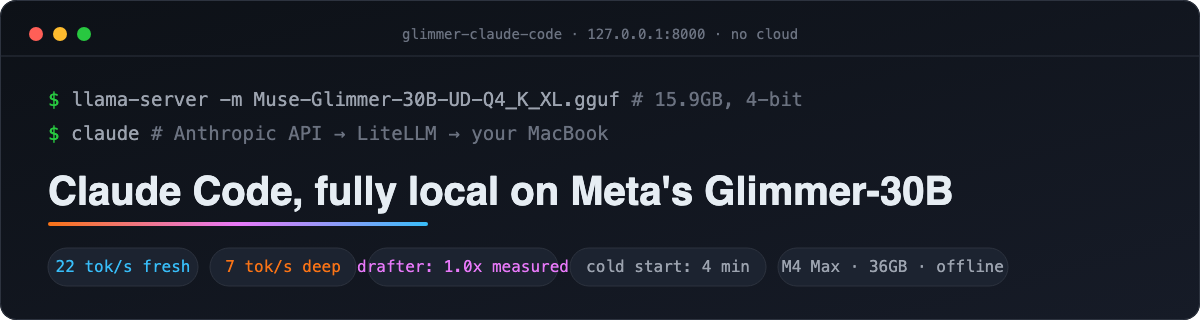 Muse-Glimmer-30B Claude Code
Muse-Glimmer-30B served locally with llama.cpp on an M4 Max, benchmarked with and without dflash speculative decoding, and connected to Claude Code through LiteLLM.
Let us build your future
Bring us a plan or just an idea. We will arrange a discovery meeting with you to go through it.