Muse-Glimmer-30B Claude Code
Meta's Muse-Glimmer-30B running locally on Apple Silicon with Claude Code
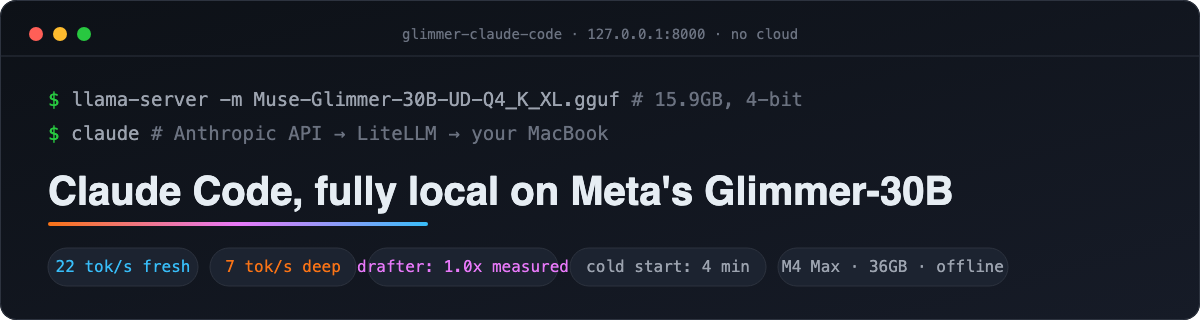
This project runs Meta's Muse-Glimmer-30B on the hardware Meta benchmarked, a MacBook Pro with an M4 Max and 36GB of memory, tests the published performance claims, and connects the model to Claude Code so a coding agent runs with no cloud service.
llama.cpp is built from source for day-one Muse-Glimmer support, then the 15.9GB 4-bit quantisation and Meta's dflash draft model are downloaded and served locally. The model is benchmarked with and without speculative decoding.
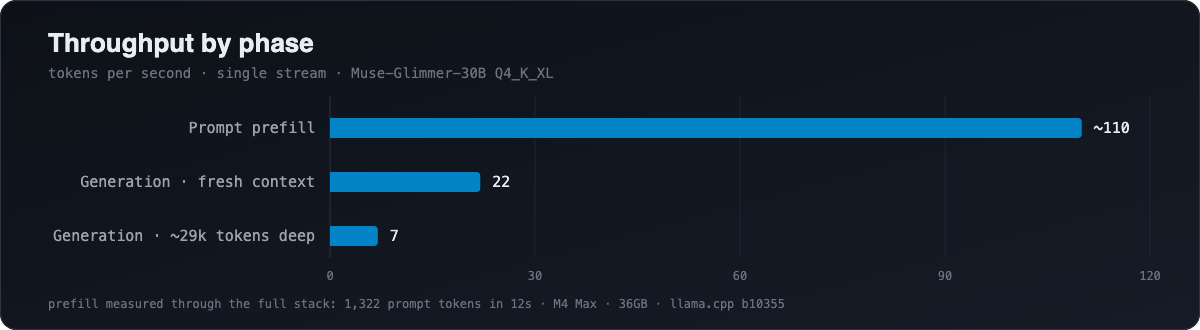
Measured on the M4 Max, generation runs at about 22 tokens per second on a fresh context and about 7 tokens per second around 29,000 tokens deep, with prompt prefill at about 110 tokens per second. dflash speculative decoding measured between 0.9x and 1.0x overall. Through Claude Code, the first response took about four minutes and later cached turns about one minute.
The repository includes the benchmark script and raw results, the server launcher, the LiteLLM configuration for Claude Code, and an HTTP agent harness.
Measured results.
- Generation, fresh context
- ~22 tok/s
- Generation, ~29k tokens deep
- ~7 tok/s
- Prompt prefill
- ~110 tok/s
- dflash speculative decoding
- 0.9x to 1.0x
- Claude Code first response
- ~4 minutes
- Claude Code later turns
- ~1 minute
More in Local AI Models.
 Your Voice
A browser application that gives a local language model examples of how you write, a brief for the piece you need, and a workspace where you refine the result together.
 Bug Hunt Benchmark
A browser application that downloads models from the Hugging Face Hub, serves them with local runtimes, and scores how well each model finds and fixes deliberate defects in small projects.
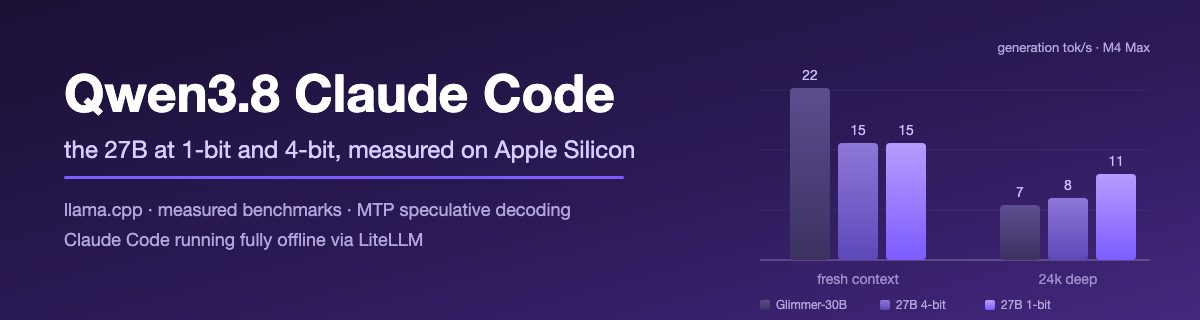 Qwen3.8 Claude Code
Qwen3.8-27B served locally with llama.cpp at 4-bit and 1-bit, benchmarked with and without MTP speculative decoding, and connected to Claude Code through LiteLLM.
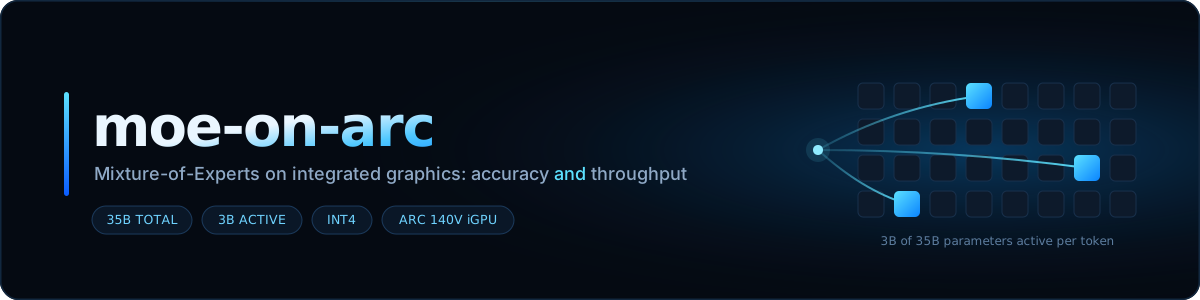 MoE on Arc
A benchmark harness that measures accuracy and throughput together, with a verified configuration for Qwen3.6-35B-A3B on an Intel Arc 140V integrated GPU through OpenVINO Model Server.
Let us build your future
Bring us a plan or just an idea. We will arrange a discovery meeting with you to go through it.